
10 free Splunk SPLK-3003 practice questions with the correct answer and a full explanation for each, taken from the CertStash pack of 133 questions. Work through them, then open each answer to check your reasoning.
Get all 133 questions (US$39) · Download these 10 as a PDF
Question 1
How does Monitoring Console (MC) initially identify the server role(s) of a new Splunk Instance?
Show answer and explanation
Correct answer: A. The MC uses a REST endpoint to query the server.
When you add an instance to the Monitoring Console in distributed mode, the MC contacts that instance over the management port and reads its server info through REST. From the returned data it determines which roles the instance is performing, such as indexer, search head, cluster manager or license manager, and pre-populates the role assignment for you. An administrator can override or add roles afterward, but the initial identification is automatic and REST based.
Why the other options are wrong
- B. Manual assignment is only an optional override after the console has already detected the roles automatically.
- C. distsearch.conf defines distributed search peer settings, not server-role assignments, so the console does not derive roles from it.
- D. The console does not blanket-assign every possible role; it reports only the roles the instance actually reports through REST.
Question 2
A customer has asked for a five-node search head cluster (SHC), but does not have the storage budget to use a replication factor greater than 2.
They would like to understand what might happen in terms of the users' ability to view historic scheduled search results if they log onto a search head which doesn't contain one of the 2 copies of a given search artifact.
Which of the following statements best describes what would happen in this scenario?
Show answer and explanation
Correct answer: A. The search head that the user has logged onto will proxy the required artifact over to itself from a search head that currently holds a copy. A copy will also be replicated from that search head permanently, so it is available for future use.
In a search head cluster, when a user accesses a search head that doesn't have a copy of a search artifact, that search head will proxy the artifact from another cluster member that holds a copy. Additionally, the artifact is replicated to the accessing search head so it becomes permanently available locally for future access, ensuring faster retrieval on subsequent requests.
Why the other options are wrong
- B. Search heads in a cluster can access artifacts from peers through proxying, so users are not denied access.
- C. Restarting search heads is not required; artifact access and replication happen dynamically without restarts.
- D. Applying the shcluster-bundle is not necessary for dispatch folder synchronization; this occurs automatically through cluster mechanisms.
Question 3
Monitoring Console (MC) health check configuration items are stored in which configuration file?
Show answer and explanation
Correct answer: D. checklist.conf
The Monitoring Console health check configuration items are stored in the checklist.conf file. This configuration file contains the definitions and settings for the various health checks that the MC performs to monitor Splunk instance health.
Why the other options are wrong
- A. healthcheck.conf is not the correct configuration file for MC health checks.
- B. alert_actions.conf is used for alert action configurations, not MC health checks.
- C. distsearch.conf contains distributed search settings, not MC health check configurations.
Question 4
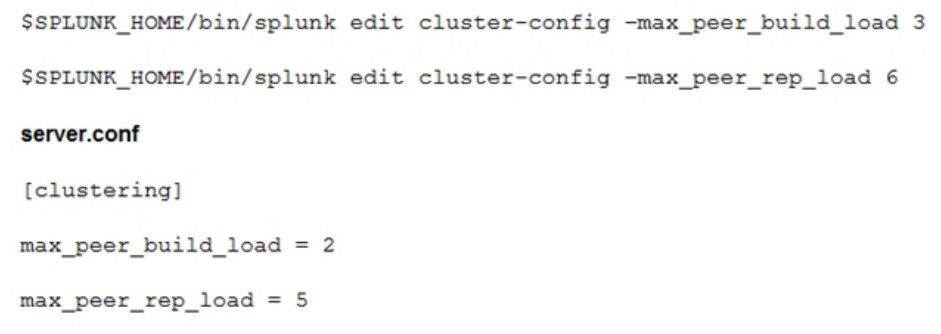
What should be considered when running the following CLI commands with a goal of accelerating an index cluster migration to new hardware?
Show answer and explanation
Correct answer: B. Network latency and storage IOPS
When accelerating an index cluster migration, the commands shown adjust max_peer_build_load and max_peer_rep_load parameters, which control the intensity of peer-to-peer replication and index building across the cluster during migration. Network latency and storage IOPS are the critical infrastructure metrics that directly impact these operations, high latency increases replication time and IOPS constraints limit the speed at which data can be written to storage during the migration process. These parameters must be tuned in consideration of the actual network and storage capabilities to avoid overwhelming either resource.
Why the other options are wrong
- A. Data ingestion rate affects the cluster during normal operations but is not the primary consideration when tuning peer load parameters during a planned hardware migration.
- C. Physical distance and location are irrelevant to the technical performance metrics controlled by these cluster configuration parameters.
- D. SSL data encryption is a security configuration that does not directly impact the performance tuning of peer build and replication loads during migration.
Question 5
Which statement is true about subsearches?
Show answer and explanation
Correct answer: D. Subsearches work best for small result sets.
Subsearches work best when processing small result sets. They are designed to generate a list of values that can be efficiently used by the outer search. When subsearches operate on large result sets, they can become a performance bottleneck because the outer search must wait for the subsearch to complete before proceeding.
Why the other options are wrong
- A. Subsearches are typically slower than other search types, not faster, especially with large datasets.
- B. Subsearches are not optimal for joining large result sets; methods like the join command or lookup tables are better suited for that purpose.
- C. Subsearches run sequentially before the outer search, not at the same time; the outer search waits for subsearch completion.
Question 6
A customer has been using Splunk for one year, utilizing a single/all-in-one instance. This single Splunk server is now struggling to cope with the daily ingest rate.
Also, Splunk has become a vital system in day-to-day operations making high availability a consideration for the Splunk service. The customer is unsure how to design the new environment topology in order to provide this.
Which resource would help the customer gather the requirements for their new architecture?
Show answer and explanation
Correct answer: D. Refer the customer to the Splunk Validated Architectures document in order to guide them through which approved architectures could meet their requirements.
Architectures document in order to guide them through which approved architectures could meet their requirements. The Splunk Validated Architectures document provides approved, tested architecture designs that meet various requirements for performance, availability, and scalability. This document is the appropriate resource for customers designing a transition from a single instance to a distributed, highly available environment, as it presents proven topologies that have been validated by Splunk.
Why the other options are wrong
- A. While docs.splunk.com contains relevant information, it is too broad and does not provide the curated, validated architecture recommendations.
- B. Engaging the sales team for licensing is premature before understanding architectural needs; architecture planning comes first.
- C. While answers.splunk.com may contain community advice, it lacks the official validation and structure of the Validated Architectures document.
Question 7
The customer has an indexer cluster supporting a wide variety of search needs, including scheduled search, data model acceleration, and summary indexing.
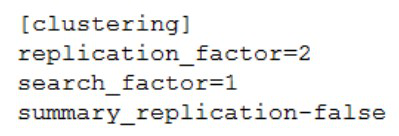
Here is an excerpt from the cluster mater's server.conf:
Which strategy represents the minimum and least disruptive change necessary to protect the searchability of the indexer cluster in case of indexer failure?
Show answer and explanation
Correct answer: B. Leave replication_factor=2, increase search_factor=2 and enable summary_replication.
The current configuration has replication_factor=2 and search_factor=1, which means data is replicated to 2 indexers but only 1 copy is searchable. If an indexer fails, searchability is lost. Option B increases search_factor to 2, ensuring at least 2 searchable copies exist at all times, protecting searchability during indexer failure. Adding summary_replication ensures summary indexing operations are also protected. This requires only configuration changes to the existing cluster without architectural redesign, making it the minimum and least disruptive change. It directly addresses the vulnerability while maintaining the current single-site topology.
Why the other options are wrong
- A. Maintenance mode prevents fix-up but doesn't solve the underlying searchability problem when an indexer fails; the failed indexer must still be recovered to restore search_factor compliance.
- C. Converting to multi-site clustering is a significant architectural change requiring site configuration, rebalancing, and operational complexity, far more disruptive than a simple parameter adjustment.
- D. Increasing replication_factor to 3 is unnecessary overhead; replication_factor=2 with search_factor=2 already guarantees searchable copies persist after any single indexer failure.
Question 8
What is the primary driver behind implementing indexer clustering in a customer's environment?
Show answer and explanation
Correct answer: D. To provide higher availability for buckets of data.
The primary driver for implementing indexer clustering is to provide high availability for buckets of data. Indexer clustering replicates data across multiple indexers, ensuring that if one indexer fails, copies of the data remain available on other cluster members, protecting against data loss and maintaining service continuity.
Why the other options are wrong
- A. Indexer clustering primarily addresses availability, not search load resiliency; search head clustering addresses search load.
- B. Indexer clustering does not reduce indexing latency; in fact, replication may add latency due to synchronization overhead.
- C. While clustering can contribute to overall environment scaling, high availability of data is the primary objective, not general performance scaling.
Question 9
In a single indexer cluster, where should the Monitoring Console (MC) be installed?
Show answer and explanation
Correct answer: C. Cluster master node
In a deployment with a single indexer cluster and no dedicated monitoring instance, Splunk recommends running the Monitoring Console on the cluster manager (master) node. The manager already tracks the state of every peer in the cluster, and it is not a search head cluster member, so enabling the console there is supported and adds minimal overhead. A separate dedicated instance is only necessary once you monitor multiple clusters or a very large deployment.
Why the other options are wrong
- A. The deployer exists to push configuration bundles to search head cluster members and is not the documented host for the console in a single indexer cluster.
- B. License manager client count does not determine console placement, and that role is not the recommended host when an indexer cluster manager is present.
- D. Running the console on a production search head competes with user searches and is not supported on a search head cluster member.
Question 10
A customer has downloaded the Splunk App for AWS from Splunkbase and installed it in a search head cluster following the instructions using the deployer. A power user modifies a dashboard in the app on one of the search head cluster members. The app containing an updated dashboard is upgraded to the latest version by following the instructions via the deployer.
What happens?
Show answer and explanation
Correct answer: D. The updated dashboard will not be available to the power user; they will see their modified version.
When an app is upgraded via the deployer and a power user has locally modified a dashboard in that app, the modified version on the search head takes precedence. The user will continue to see their customized dashboard rather than the updated version from the upgraded app, as local modifications are preserved to avoid overwriting user customizations.
Why the other options are wrong
- A. The bundle deployment will not fail due to local modifications; instead, local changes are preserved and take precedence.
- B. Applying the search head cluster bundle will succeed; local modifications do not cause deployment failures.
- C. The updated dashboard will not be available to the power user; their local modification takes precedence over the app upgrade.
That was 10 of 133.
The full Splunk SPLK-3003 pack has all 133 questions, each with the answer, the explanation and why the other options are wrong, plus a questions-only copy for timed runs. US$39, paid once, with free monthly updates and a pass-or-your-money-back guarantee.